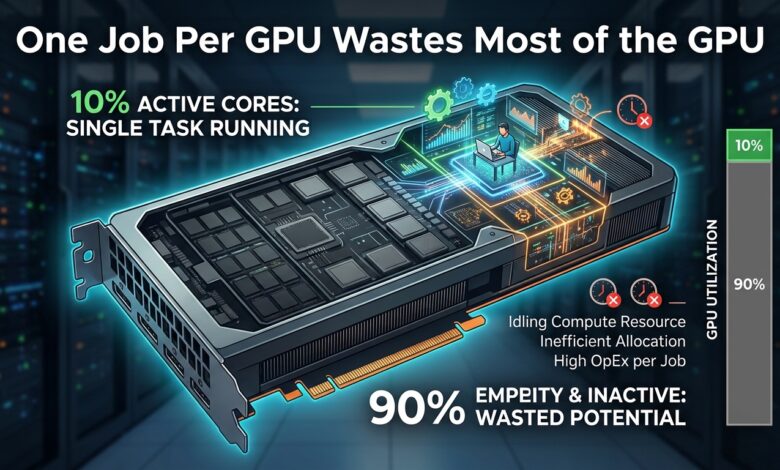
Key takeaway: Most GPU workloads use a fraction of the device they hold. Sharing mechanisms exist at several levels, and the right one depends on whether you need isolation or just utilisation.
Where the Waste Occurs
A training job allocated a whole GPU is idle whenever it is not computing — waiting on data loading, executing Python between steps, synchronising across workers, or checkpointing to storage.
Measured utilisation for a typical unoptimised training job frequently sits between thirty and sixty percent. Inference is often worse: a model serving low request volume holds a device that is busy for milliseconds at a time.
Development workloads are the extreme case. A notebook attached to a GPU while someone reads documentation holds an expensive device at zero percent utilisation for hours.
The Sharing Options
| Mechanism | Isolation | Best for |
|---|---|---|
| Time slicing | None — jobs interleave | Development, bursty inference |
| MPS (multi-process service) | Weak | Many small concurrent kernels |
| MIG (multi-instance GPU) | Hardware-partitioned | Multi-tenant, predictable |
| Whole device | Complete | Large training, latency-critical |
Time slicing lets multiple processes submit work that the driver interleaves. It is simple to enable and provides no memory isolation, so one process can exhaust memory and crash the others. Acceptable for development and cooperative workloads.
MIG partitions the physical device into instances with dedicated memory and compute slices. A job in one instance cannot affect another, which makes it suitable for multi-tenant use. The partitioning is fixed at configuration time, so instance sizes must be chosen in advance and reconfiguration requires draining the device.
MPS allows kernels from different processes to run concurrently rather than interleaving, which improves utilisation for workloads with many small kernels. Isolation is weaker than MIG.
Improving Utilisation Before Sharing
Sharing a badly utilised job means two badly utilised jobs. Fixing the underlying inefficiency usually delivers more.
Data loading is the most common bottleneck. A GPU waiting on a single-threaded loader reading from remote storage is a solvable problem: increase worker count, prefetch, pin memory, and cache locally.
Batch size is the second lever. Larger batches amortise per-step overhead and improve memory bandwidth efficiency, and many jobs run with a batch size chosen arbitrarily early on.
Mixed precision typically improves throughput substantially on hardware with tensor cores and is frequently left unenabled.
Measure before deciding. Utilisation over time, plus a profile showing where step time goes, distinguishes a job that needs a bigger batch from one that needs faster data loading — and those have different fixes.
Queue Design
For a shared cluster, separate queues by workload shape rather than treating all jobs alike. Interactive development gets time-sliced fractional allocations. Training gets whole devices with a maximum duration. Inference gets MIG instances sized to the model.
Enforce a time limit on interactive allocations and reclaim idle devices automatically. Without that, a small number of forgotten notebooks consumes a large share of the fleet, which is the most common cause of GPU scarcity in practice.
The Bottom Line
Profile utilisation before adding capacity, fix data loading and batch size first, then share with time slicing for development and MIG where isolation matters. Reclaim idle interactive allocations automatically, because forgotten sessions are usually the largest single source of waste.


